

The pilot still had a Slack channel. Three months after the demo day, the same people were still “validating.” Nobody had written what success meant in one sentence. Nobody owned the week after go-live. Ops had not been invited to the workshop that started it. Risk had a slide, not a signature. The model looked fine in the sandbox. The program looked fine in the steering deck. Nothing was wrong enough to kill, and nothing was ready enough to run.
That is pilot forever. It is the quiet failure mode of enterprise AI, and it is what good AI project delivery is built to prevent.
This post is a delivery shape, not a tool tutorial. Phases, exit criteria, and ownership from a discovery workshop through hypercare and an ops handoff. The point is to make the next gate a decision, not another month of “promising results.”
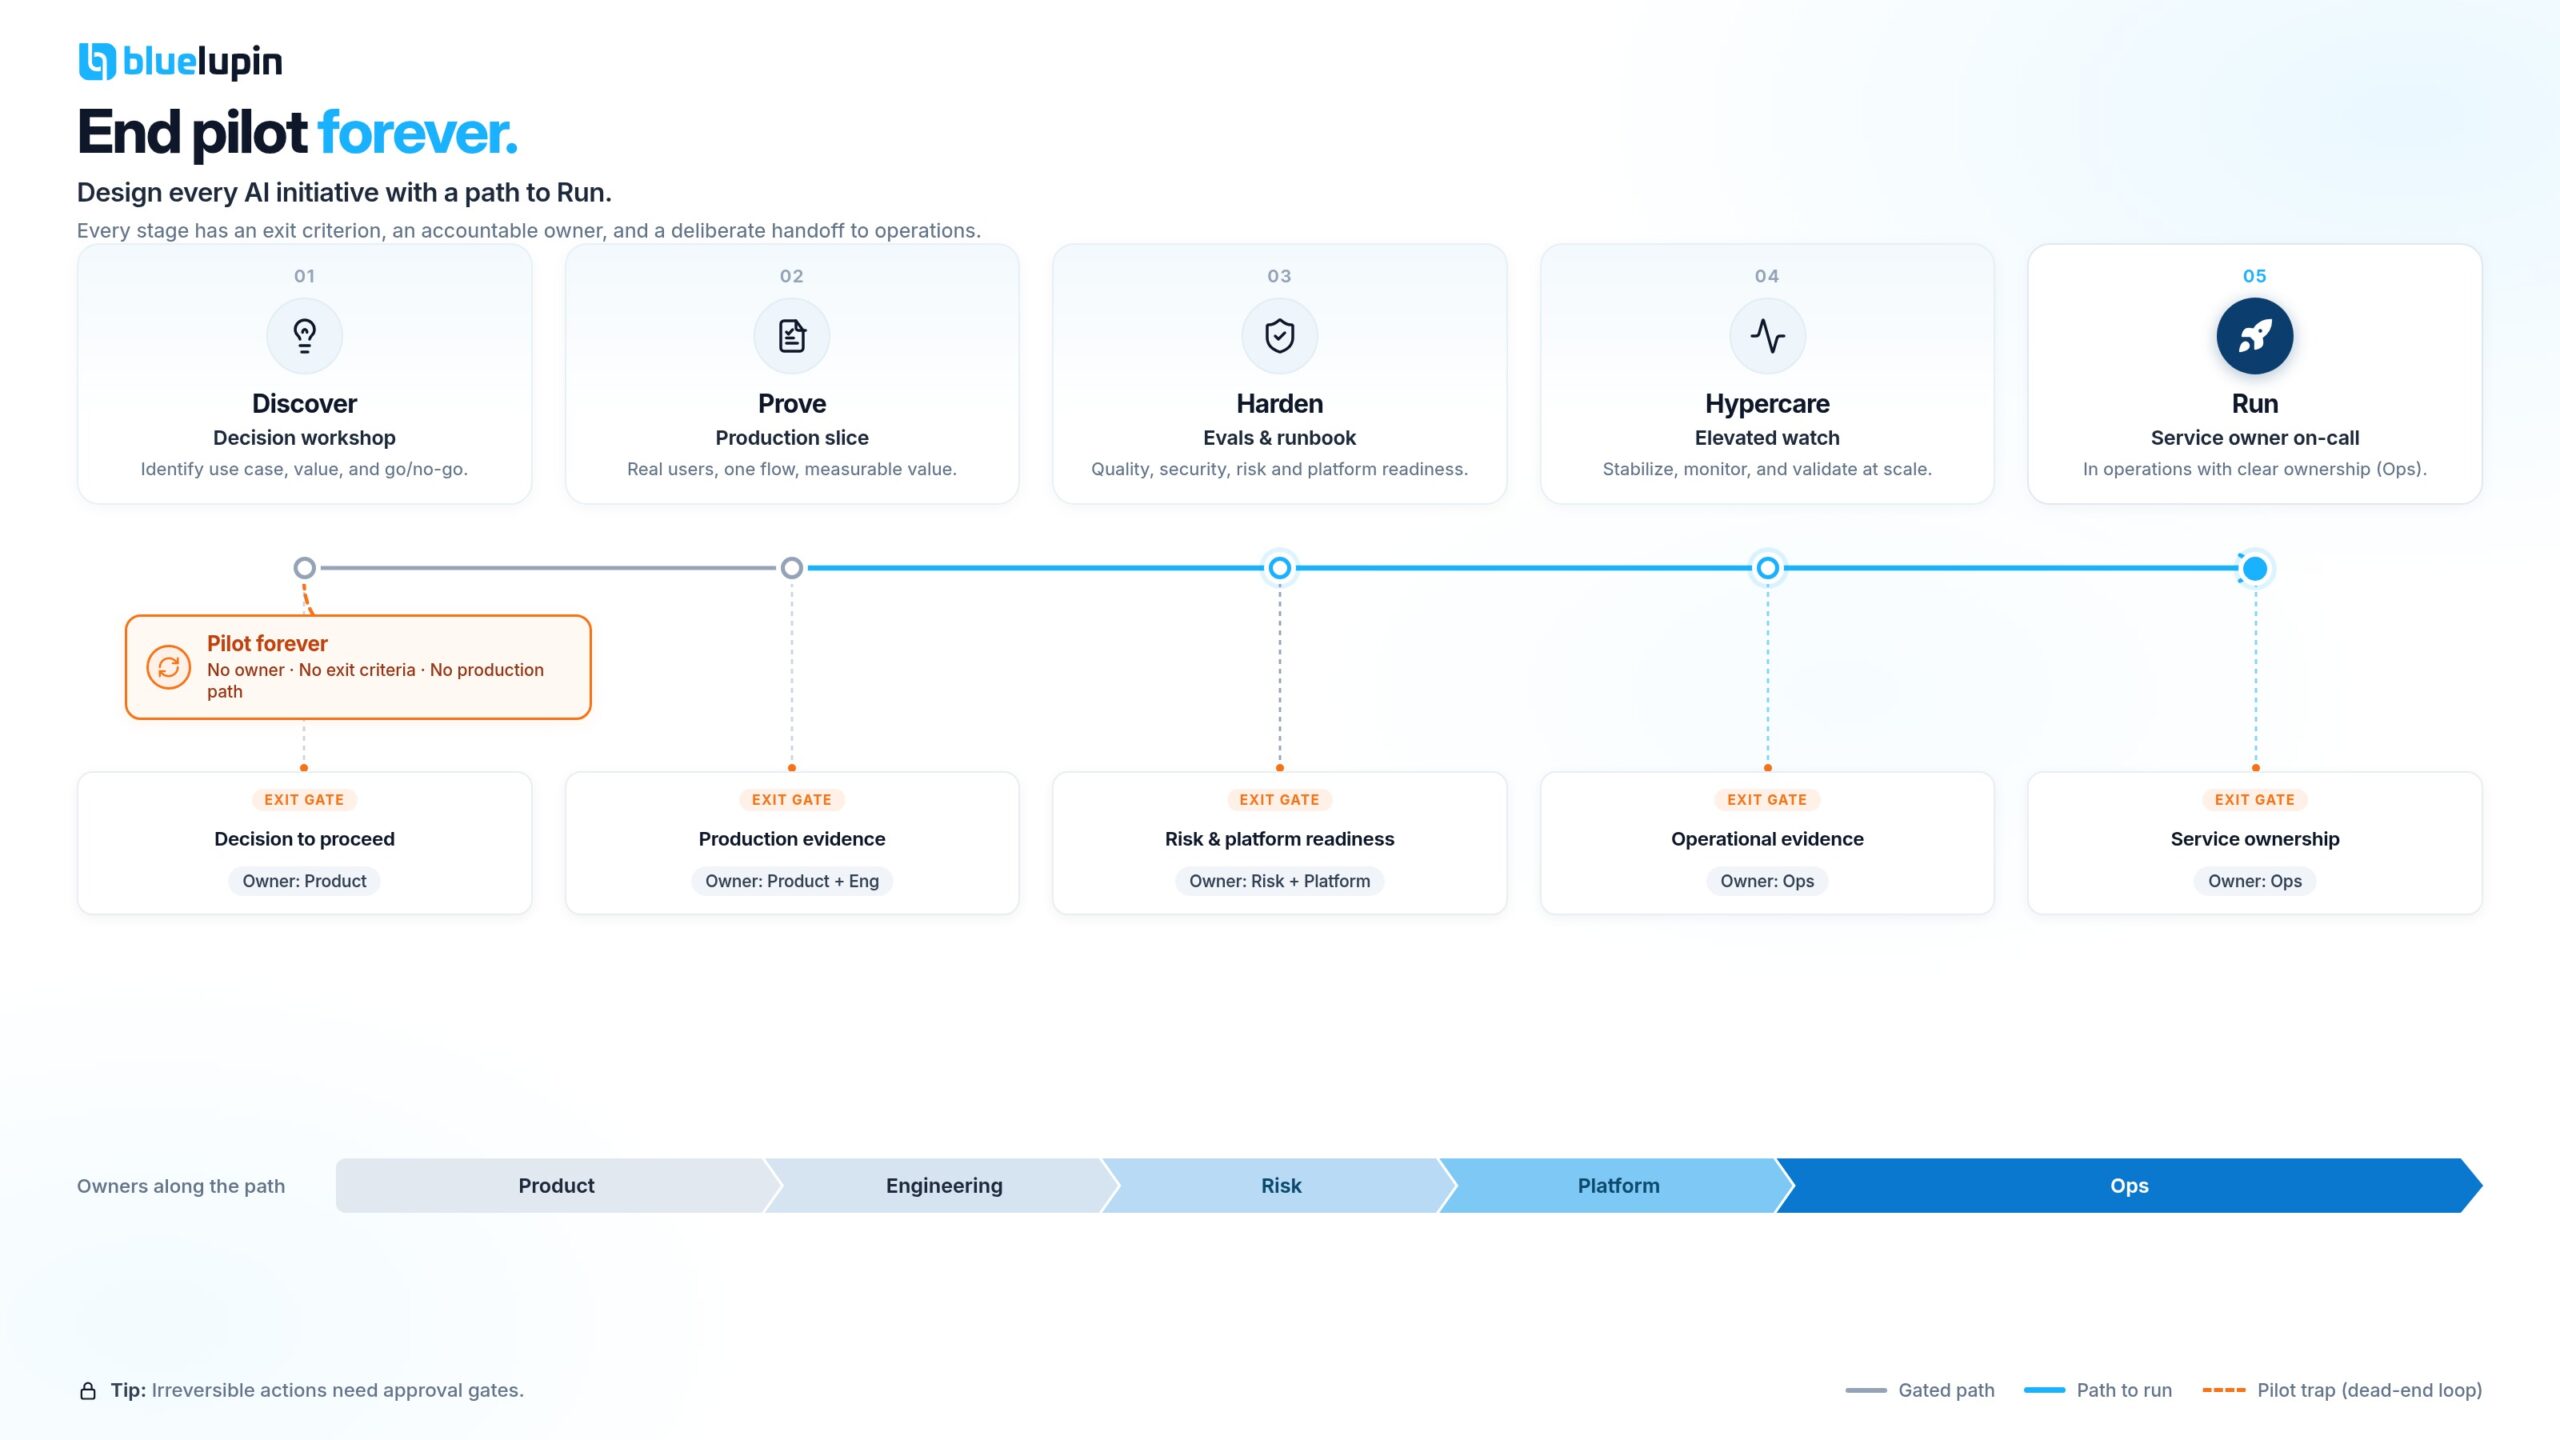
The failure mode: pilot forever (no exit, no owner, no ops)
Most AI programs do not die in a dramatic board vote. They stall. The demo impressed. Funding continued as a line item named “AI exploration.” Legal was looped in late. The business sponsor rotated. End users were shown a happy path once and never asked to live with the exceptions. Success metrics stayed soft (“improve productivity”) so nobody could fail the gate honestly.
Practitioners keep describing the same stall. Organizations stay stuck in piloting while boards ask for scale, and the gap is rarely “the model cannot answer.” Thoughtworks frames it as a path-to-production problem: an operating model from idea through funding, discovery, and continuous production, not a one-off engineering pipeline (Thoughtworks on path to production). InformationWeek’s take from Silicon Foundry is blunt for a different reason. How you run the pilot is the scale move. Change management, stakeholder alignment, and business-aligned metrics have to be built during the pilot, or a technically fine proof of concept still cannot clear the last mile (InformationWeek on pilots that never reach production).
Three missing pieces create pilot forever:
- No exit. The phase ends when the calendar says so, or when enthusiasm fades, not when evidence says go, kill, or re-scope.
- No owner. Product owns the story. Eng owns the repo. Risk owns a review. Ops owns nothing until something breaks in production. Then everyone owns the incident.
- No ops path. Monitoring, on-call, runbooks, and a change process for model, prompt, tool policy, or agent behavior are “phase two.” Phase two never starts.
You prevent that by writing the shape before the workshop ends. Discovery that produces a decision. A thin production slice with real users and real controls. A harden pass. Hypercare with exit criteria. Then run.
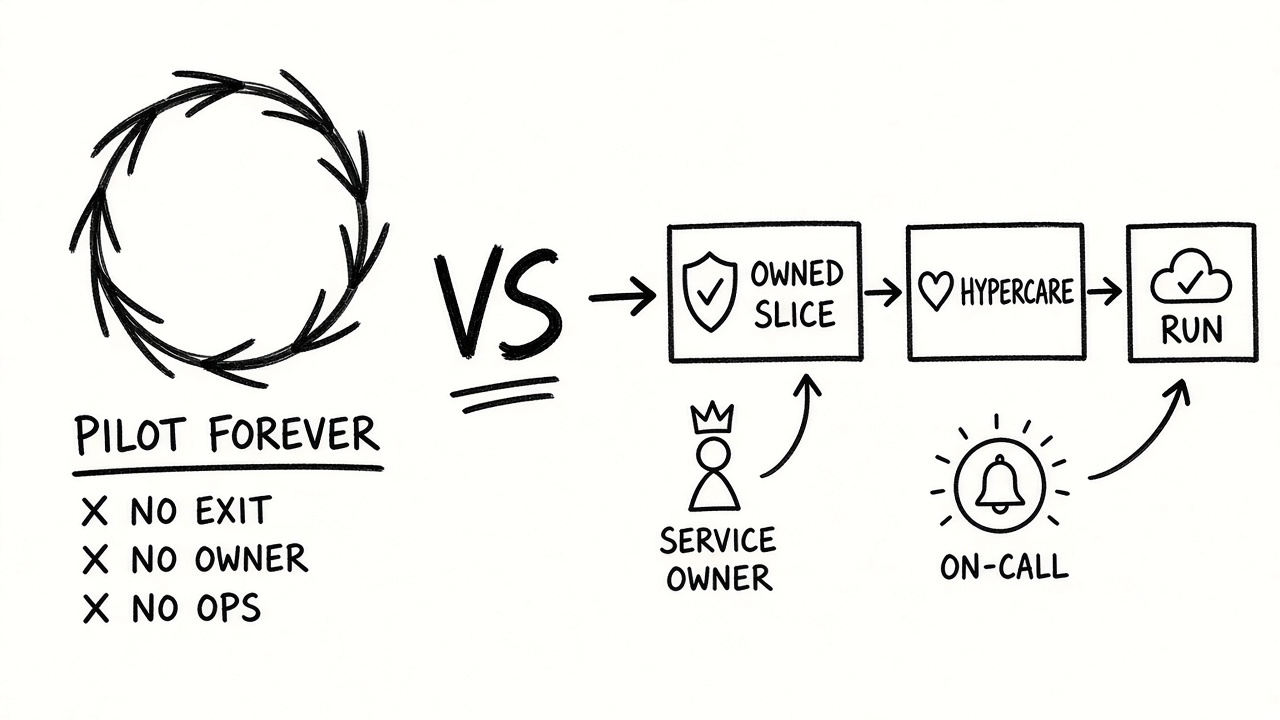
The shape at a glance: discovery → thin production slice → harden → hypercare → run
A good AI delivery lifecycle is gated and boring on purpose. Fancy architecture does not substitute for a named next gate.
| Phase | Purpose | What “done” means |
|---|---|---|
| Discovery | Frame the problem, blast radius, and success metric | Written go / no-go / re-scope with a sponsor signature |
| Thin production slice | One workflow, real users, real controls | Live path under limited blast radius, not a deck |
| Harden | Make the slice survivable | Evals, monitoring hooks, NFRs, draft runbook, risk sign-off |
| Hypercare | Stabilize after cutover with elevated attention | Exit criteria met; ops independence rising |
| Run | Business as usual | Named on-call, change process, accepted residual risk |
That table is the short answer to “what are the phases of an AI project from discovery to production?” The rest of this post makes each gate checkable.
Straive and others describe the same idea as designing the pilot as a production rehearsal: real data characteristics, real integrations, security and logging from the start, load that resembles production (Straive pilot-to-production roadmap). We prefer “thin production slice” over “pilot” in the roadmap language because “pilot” has become a word people hide under. If it cannot touch a real workflow under controls, it is still a demo.
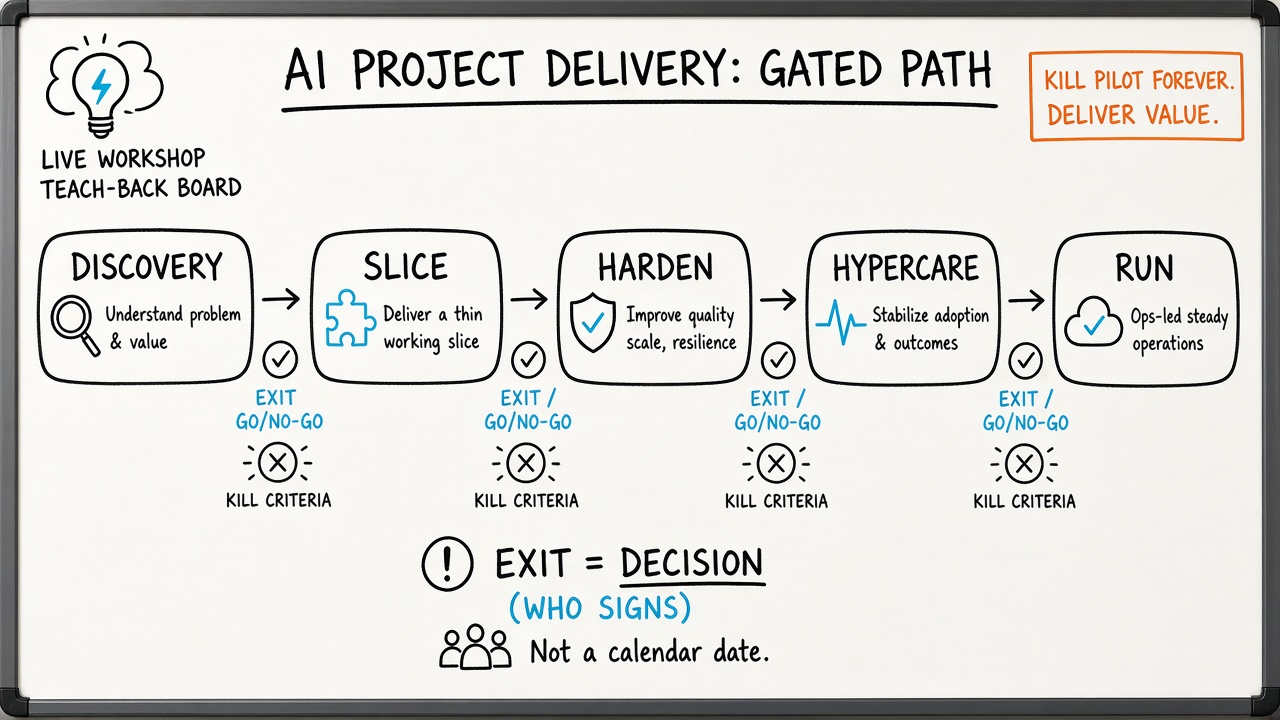
Discovery that produces a decision, not a deck
Discovery for AI programs fails when it produces forty slides and zero decisions. Useful discovery ends with three artifacts on one page:
- Problem. Which decision or workflow improves, for whom, measured how. Not “explore GenAI for customer service.” Prefer “reduce time-to-first-draft on Tier-2 replies for the claims desk, with human send.”
- Blast radius. What the system can read, draft, or do. Read-only citation is one risk class. Draft-for-human is another. Tool calls that move money or change citizen records are another. If irreversible actions are in scope, the control story starts here, not after the model is “good enough.” We already wrote the go-live control pattern for that class as approval gates for AI agents.
- Success metric. One primary metric the sponsor will defend in a funding review. Secondary health metrics (latency, refusal rate, escalation rate) sit beside it. If you cannot name the primary metric, you are not ready to build.
Add a fourth line when it is true: kill criteria. What evidence ends the investment without drama. Missing kill criteria is how pilots become perpetual.
Discovery exit is a meeting with a written outcome: go, no-go, or re-scope. The business sponsor signs. Risk/compliance initials the blast-radius class. Eng initials feasibility and data access reality. Product owns the problem statement. If any of those signatures are “we’ll sort it in build,” discovery did not finish.
Exit criteria worth writing down (per phase; who signs)
Exit criteria are how you move an AI pilot into production without lying to yourself. Write them before the phase starts. Review them against evidence. Calendar dates are review points, not automatic authority to exit. That is the same discipline ITIL-flavored Early Life Support teams use when they refuse to end hypercare because “thirty days passed” (ITILigence on Early Life, hypercare, and warranty).
| Phase | Exit criteria (checkable) | Who signs |
|---|---|---|
| Discovery | Problem, blast radius, primary success metric, and kill criteria written; data access path named; owner for the slice named | Business sponsor (go/no-go); risk/compliance (blast-radius class); eng (feasibility) |
| Thin production slice | One workflow live with real users under the agreed blast radius; controls on irreversible actions enforced outside the prompt; primary metric instrumented; known issues list owned | Product (user path); eng (runtime + controls); risk (gate policy for the action class) |
| Harden | Eval suite for the workflow; monitoring and alerts for technical and business signals; rollback or disable path tested; draft runbook and on-call nomination; residual risks accepted or mitigated | Eng + platform (operability); risk (acceptance of residual risk); ops (willingness to receive handoff) |
| Hypercare | Exit criteria package met on evidence (see Hypercare section); open P1s closed or formally accepted; recurring defect themes labeled and owned; ops resolving routine issues without the build team | Ops lead + product (handoff); eng (defect closure); sponsor (accept residual) |
| Run | Service owner named; on-call rota live; model/agent/prompt/tool-policy change process published; warranty or project obligations closed or transferred | Service owner (BAU accept); ops (support model); product (backlog ownership) |
If a phase cannot produce a signature, it cannot produce a next phase. That is the whole anti-pilot-forever mechanism.
Ownership map: product, eng, risk/compliance, platform, ops
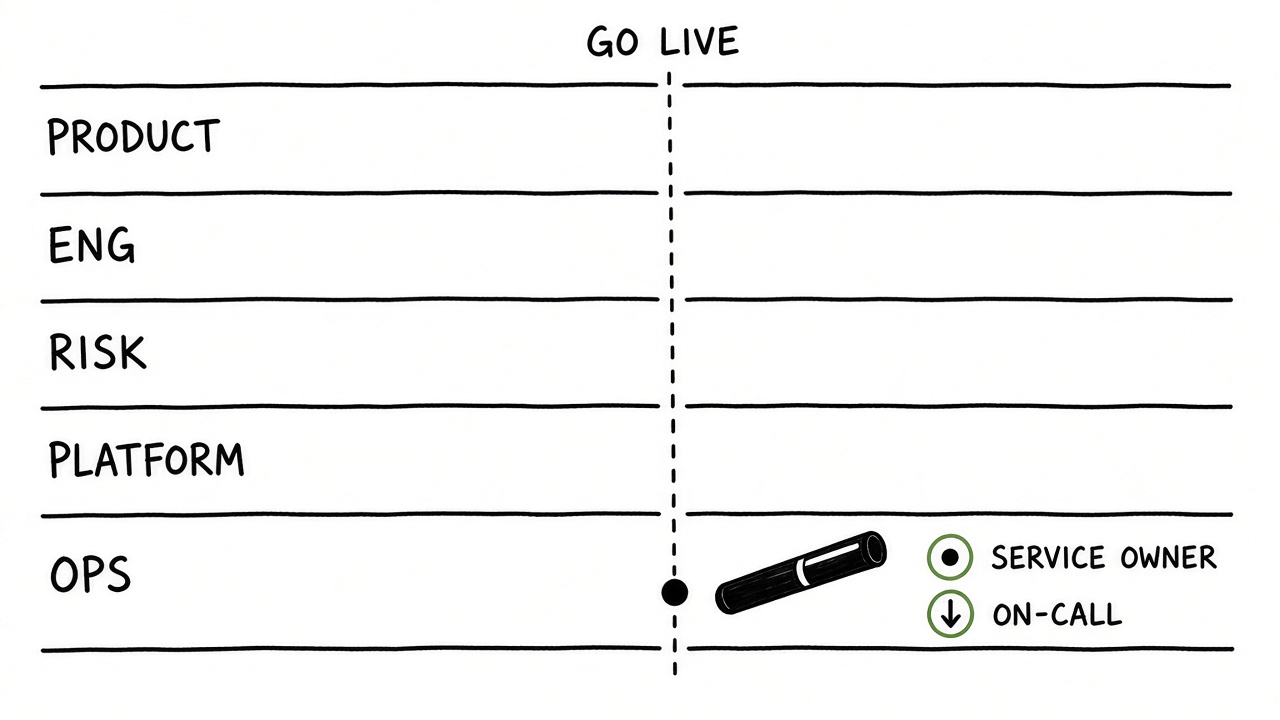
“Who owns what between product, eng, risk, and ops?” is not a RACI slide for the appendix. It is the difference between a demo and a service. Platform sits in the middle for shared runtimes, identity, evals infrastructure, and policy enforcement.
| Concern | Product | Eng | Risk / compliance | Platform | Ops |
|---|---|---|---|---|---|
| Problem and success metric | Owns | Advises feasibility | Advises constrained outcomes | Advises shared patterns | Consumes metric for run |
| Blast radius and action class | Co-defines with risk | Implements tool boundary | Owns policy class | Provides enforcement hooks | Escalates violations |
| Thin slice scope | Owns user path and adoption | Owns build and integration | Gates irreversible classes | Supplies shared services | Shadows early |
| Evals and quality bar | Defines “good enough” for the workflow | Implements eval harness | Sets red lines (safety, privacy) | Hosts shared eval runners | Watches production eval drift |
| Go-live controls | UX for pending / explain | Runtime pause before side effect | Policy for auto / human / dual / deny | Gateway or broker patterns | Queue staffing in hypercare |
| Hypercare | Adoption and comms | Defect fix with build context | Spot-checks audit and consent gaps | Capacity and cost signals | Owns elevated support cadence |
| Run / BAU | Backlog and value reviews | Change delivery under process | Periodic assurance | Platform SLOs | On-call and incident command |
| Model / agent / prompt / tool-policy change | Approves product impact | Implements and versions | Approves risk-tier changes | Pipeline and rollback tooling | Accepts change into rota |
One named service owner must exist before harden ends. Committees do not take pages at 2 a.m.
The production slice: one workflow, real users, real controls
How do you move an AI pilot into production? You stop calling it a pilot and you ship a slice.
One workflow. Not five use cases “to maximize learning.” One path a real role runs weekly. Exceptions are first-class: the happy path alone is how demos lie.
Real users. A named cohort, not the project team pretending to be the desk. Feedback channels and override paths are part of the product. If users will not trust the output, InformationWeek’s trust bottleneck is already your schedule (InformationWeek).
Real controls. Identity-bound tools. Audit of proposals and decisions. For mutating actions, a pause before execute with the exact args visible to a reviewer. That is the approval gates pattern: keys say can, gates say should. Shadow or log-only on a mutating class before enforce, then promote by action class. Do not flip all writes on because the steering committee liked the demo.
The slice should leave reusable artifacts: integration stubs that become production connectors, eval cases drawn from real tickets, monitoring hooks, and a defect theme list. If the slice is thrown away and rebuilt for “real production,” you ran a demo with better lighting.
When the slice sits on the edge of a legacy core, keep the delivery question separate from the rewrite question. Strangler-shaped edges are a sibling topic. This post only insists the edge you ship is owned, measured, and controlled.
Hypercare: what you watch, how long, what triggers rollback or scale
What is hypercare in an AI program? Borrow the ITSM meaning, then add AI-specific watches.
In Early Life Support language, hypercare is the intensive period after cutover: frequent reviews, rapid incident response, delivery and support side by side, active user-experience monitoring, and accelerated decisions while the builders are still available (ITILigence). Supportbench’s framing matches what enterprise buyers already know from ERP and CRM cutovers. Go-live is an event. Hypercare is the stabilization period that follows. BAU is what you hand to when exit criteria hold, not when the calendar expires (Supportbench on hypercare). Hypercare that never ends is understaffed BAU with better branding.
For AI programs, watch both layers:
Service / ITSM layer
- Incident volume and severity against an agreed baseline
- Time to acknowledge and resolve under elevated targets
- Recurring defect themes (label them; do not treat every ticket as unique)
- Adoption: are users in the workflow, or avoiding it?
AI / agent layer
- Primary business metric vs discovery baseline
- Refusal, escalation, and override rates
- Eval sample on live traffic (offline eval alone drifts silently)
- Cost and latency per successful task
- Control health: pending-approval queue depth, timeout/deny rates, auditor sampling of approvals
- Data or behavior drift signals that should trigger investigation, not vibes
How long? Plan a review window (many transformation teams use a short intensive window, then a taper). Exit on evidence. Useful AI-adapted exit package, all true for an agreed consecutive-day window:
- No open P1s; P2s owned with dates
- Ticket or incident volume within an agreed band of projected BAU
- No new recurring defect theme in the window
- Ops resolving routine class issues without the build team on every thread
- Primary metric moving in the agreed direction or an accepted explanation with a dated plan
- Critical workarounds documented and owned
- Product and ops sign the handover summary
Rollback or scale triggers (name them before cutover):
- Rollback / disable: control failure (gate bypass, audit gap), safety or compliance breach, primary metric collapse with no accepted mitigation, cost blow-up past an agreed ceiling
- Hold: metric flat, defect themes still opening, ops still dependent on builders
- Scale: exit criteria met, residual risks accepted, capacity and cost model hold under the next cohort
If the project team vanished tomorrow, would ops still be confident? That question ends hypercare better than any slide titled “Week 4.”
Handoff to run: runbooks, on-call, model/agent change process
Run is not “the project closed.” Run is Business as Usual inheriting confidence.
Runbooks that match production, not the design doc. Include: how to disable the agent or tool class; how to drain the approval queue; how to roll back a prompt, model version, or policy pack; who to call for data poisoning or jailbreak-class incidents; where eval dashboards live.
On-call with a rota that includes someone who can change the runtime, not only restart a pod. Page severity should distinguish “model quality degraded” from “broker cannot enforce policy” from “downstream system outage.” Those are different playbooks.
Model / agent change process. Treat prompt packs, tool allowlists, risk-tier matrices, and model versions as change-controlled artifacts. Same spirit as Google-style MLOps thinking: validation before promote, monitoring after, ability to roll back (Google Cloud MLOps overview). For agent systems, a “model bump” that silently widens tool blast radius is a product change, not a library bump. Risk signs tier changes. Product signs user-visible behavior changes. Ops accepts into the rota.
Warranty language (internal or supplier) should end on conditions, not only on a date. Unresolved items become owned backlog or accepted residual risk. Do not smuggle a second pilot inside “we’ll keep the war room a bit longer.”
How we run this shape with enterprise buyers
At Bluelupin we treat AI project delivery as a gated operating shape, not a demo calendar. Discovery is a decision workshop with blast radius and kill criteria on the page. The first ship is a thin production slice with real users and real controls. Harden is where evals, monitoring, and the draft runbook stop being optional. Hypercare is staffed and exited on evidence. Run has a service owner and a change process for the things that will keep moving: models, prompts, tools, and policy.
We do not promise a magic “AI factory” switch. We practice the discipline that ends pilot forever: exits, owners, and an ops handoff you can defend when the builders leave the channel.
If you are sitting on a promising pilot with no exit criteria and no named ops owner, start there. Write the next gate before you fund another month of validation.