

Last quarter a release train that used to ship every two weeks started landing almost every other day. The stand-up charts looked healthy. Chat was full of green checkmarks. Then support opened three tickets with the same smell: the product answered like it was right, the suite stayed green, and a real user still got hurt.
One was a payment edge case. The agent had “covered” it with a test that asserted the mock was called, not that money moved. Another was a chat feature that scored well on a demo prompt and fell apart on a dialect our fixture set never saw. A third was a self-healed Playwright locator that papered over a real layout bug until a customer on a small laptop hit it.
We did not lose QA. We lost the old shape of the bug. Plausible-but-wrong replaced obvious-red. Fake-green joined the defect classes we already knew. AI product behaviour needed judges and eval harnesses, not only page objects. This is how we think about that shift on Bluelupin programmes: roles, tools, techniques, and the work we still refuse to hand to a model.
What QA used to mean (briefly)
For years the story was familiar. Manual cycles found the weird stuff. Automation regression protected the known paths. A QA engineer owned suites, environments, and the awkward conversation when “works on my machine” met production.
That craft still matters. Selenium and Playwright suites, exploratory sessions, risk-based sampling, and production telemetry did not become obsolete because a model can write a describe block. What changed is the volume of code under test, how fast we can author coverage, and the failures that look like success until you look sideways.
If you only remember the nostalgia version (click paths forever, agents nowhere), you will fight the wrong war. The useful memory is simpler: QA owned the oracle for “done,” not the monopoly on keystrokes.
Three shifts, not one tool fad
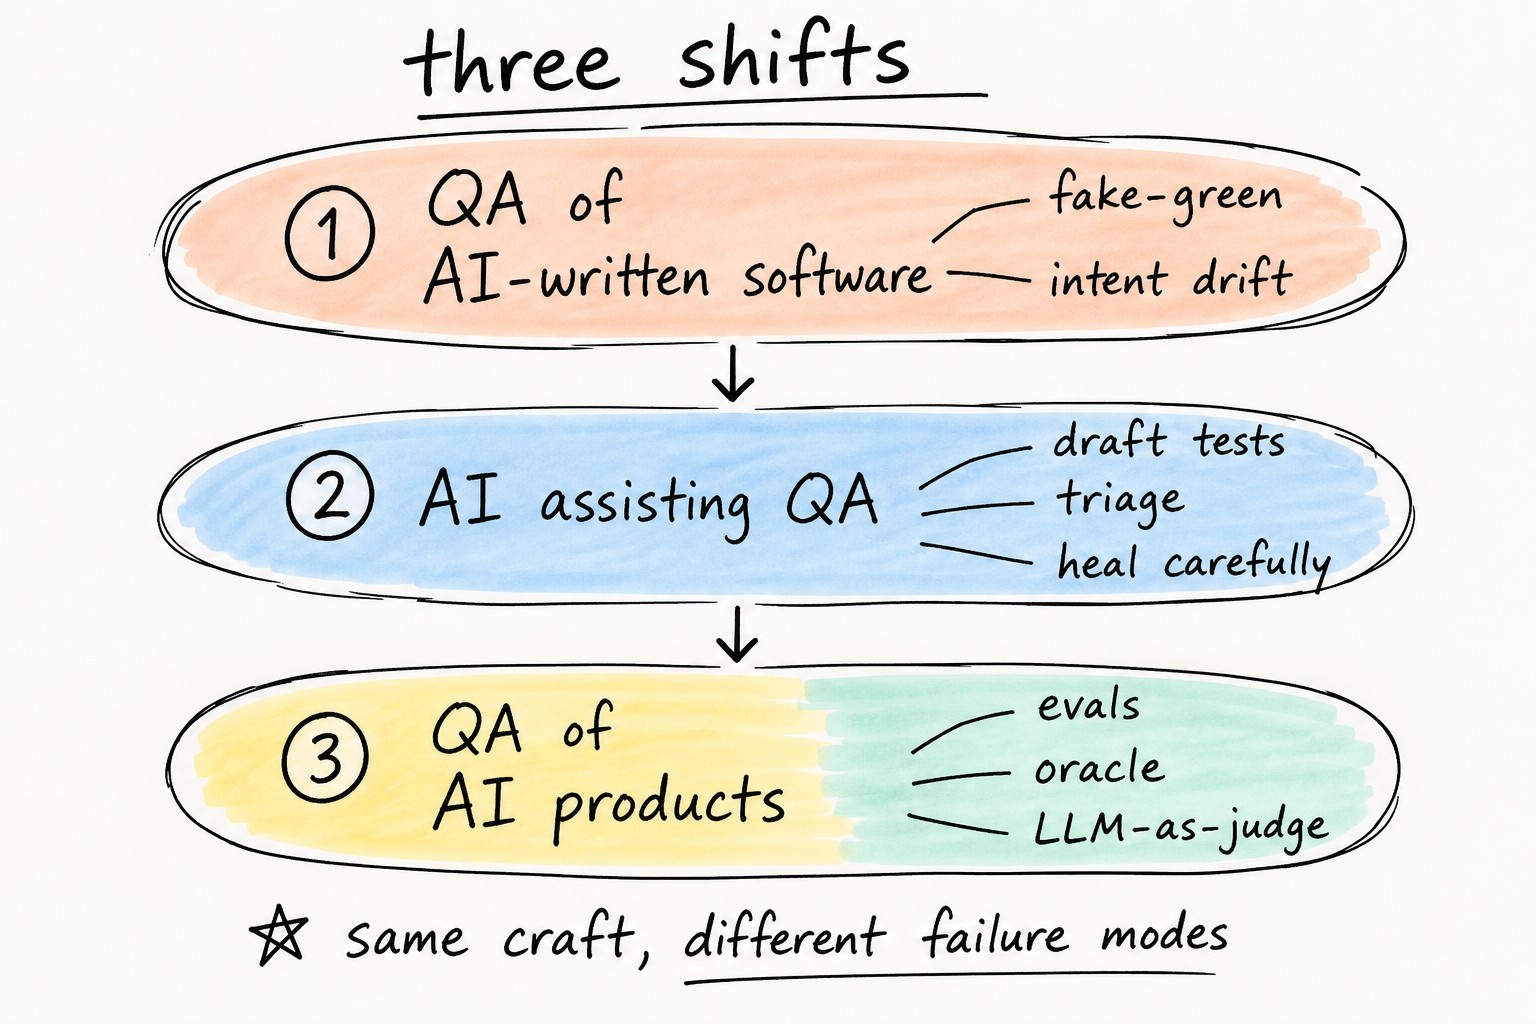
We keep splitting the conversation into three lanes. Mixing them is how teams buy a visual AI plugin and pretend they have an AI-product evaluation strategy.
1. QA of AI-written software
Agents draft most of the diff on programmes we run. The risk is not ugly code. The risk is silent wrongness: empty asserts, always-true tests, deleted cases, over-mocks, hallucinated packages, and “refactor only” claims that quietly touch auth.
Industry checklists for testing AI-generated code rhyme with what we already do on high-risk PRs. Scope the diff against the ticket. Keep deterministic build and lint gates. Demand behavioural proof the agent did not author alone. Scan secrets and supply chain. Reserve human attention for money, identity, and irreversible actions. Generation is untrusted input. A green suite the same agent wrote is not independent evidence.
2. AI assisting QA work
This is the lane vendors love: generative drafts of tests, visual diff helpers, self-healing locators, ML models that cluster flakes, and planner / generator / healer loops like the ones Playwright documents for exploring an app, turning a plan into specs, and repairing failures.
We use that lane. We also treat healer output as a diff that needs a human eye. A locator that “heals” into silence can hide a product bug. Flake classifiers help triage; they do not get merge authority. Generative drafts are a starting point for review, not a certificate.
3. QA of AI products and features
Chat, agents inside the product, ranking, summarisation, and tool-calling flows do not fail the way a broken form fails. They fail on tone, omission, unsafe tool use, or drift when the model or prompt changes. The technique set expands here: golden tasks, rubrics, LLM-as-judge where scores are calibrated against human labels, pairwise evals when you change a system prompt, and deterministic graders that still run first.
If your “AI QA” plan is only screenshot diffs on a marketing site, you are not in this lane yet.
Tools and techniques map
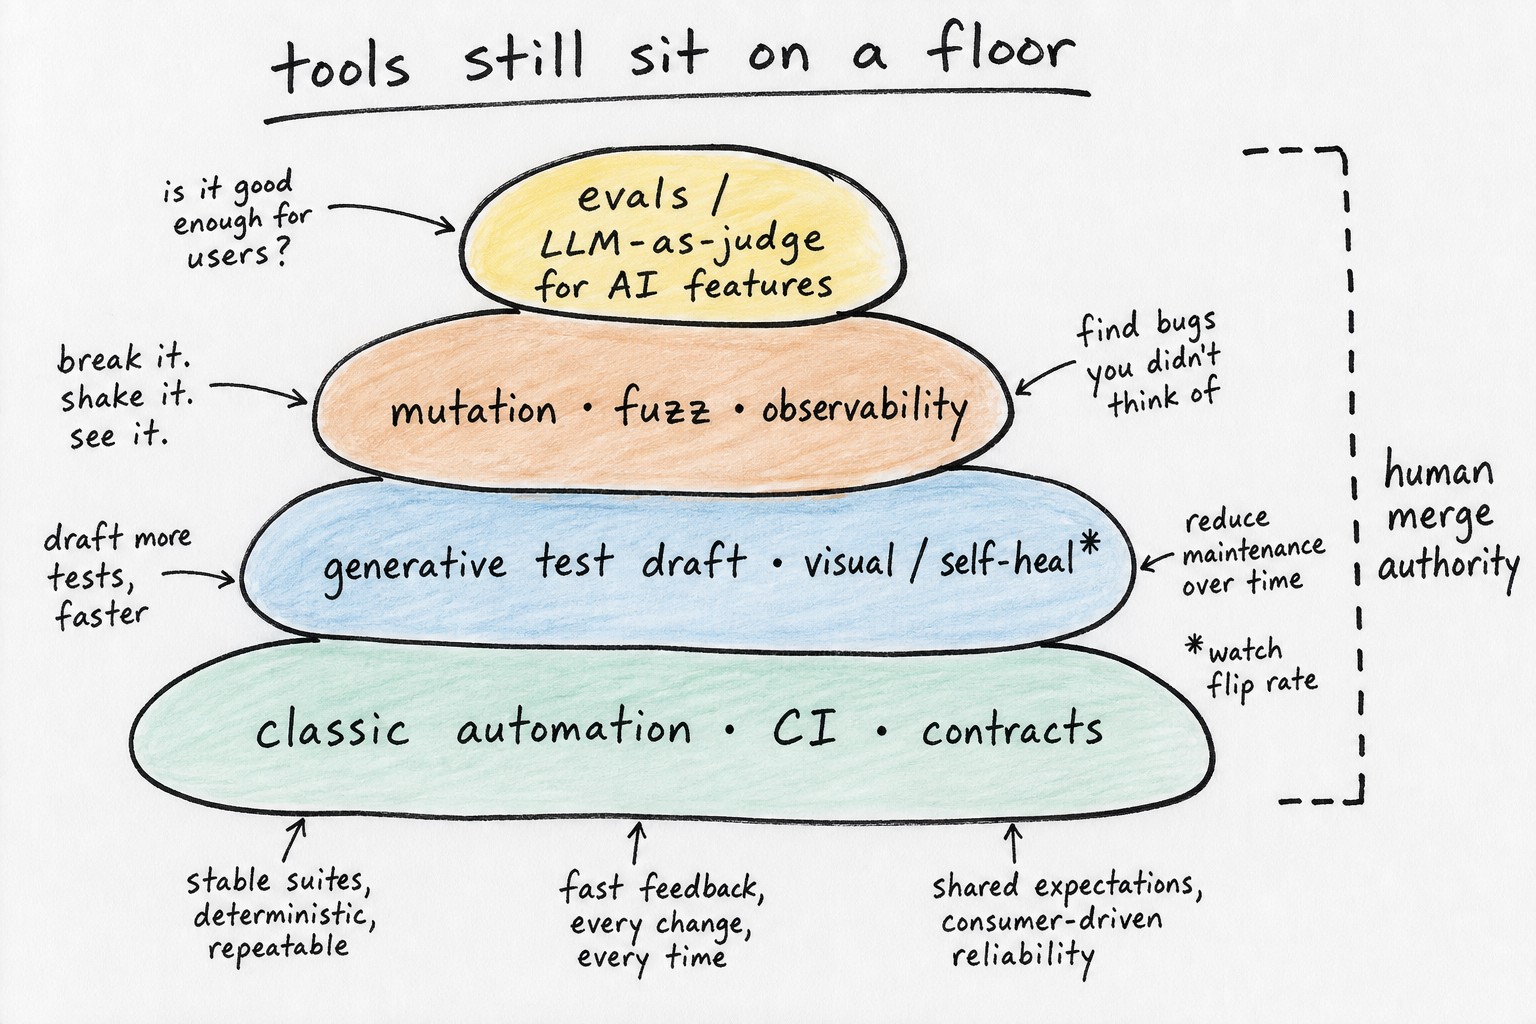
We do not throw away the foundation. We add layers with clear jobs.
| Technique | What it is good for | Honest limit |
|---|---|---|
| Classic automation (unit, API, browser) | Known paths, contracts, regressions | Weak against plausible-but-wrong and empty asserts |
| Generative test drafting | Coverage ideas, first drafts from a reviewed plan | Same-model theatre if the agent grades its own work |
| Visual / self-heal | Locators and layout churn | Can heal a real bug into a quiet green |
| Property / fuzz | Invariants and weird inputs agents miss | Needs clear properties; not a substitute for intent |
| Contract tests | Boundaries agents love to invent twice | Only as strong as the contract you wrote |
| Mutation testing | Suite honesty on agent-touched modules | Costly; use on hot modules, not everywhere |
| Observability + production QA | Drift after ship, real traffic shapes | Needs ownership and rollback, not only dashboards |
| LLM-as-judge / eval harnesses | Chat, agents, rubric-scored behaviour | Calibrate or you measure vibe; never override hard gates |
| Risk-based human review | Auth, money, privacy, irreversible actions | Finite attention; tier the PR, not the model brand |
Playwright’s planner / generator / healer loop is a concrete example of lane 2 done carefully: plans and patches are reviewable artefacts, not invisible magic in CI. Eval harnesses for coding agents and for product LLMs are the lane 3 cousin: fixed tasks, structured verdicts, and a human-owned rubric.
What we refuse to outsource to a model
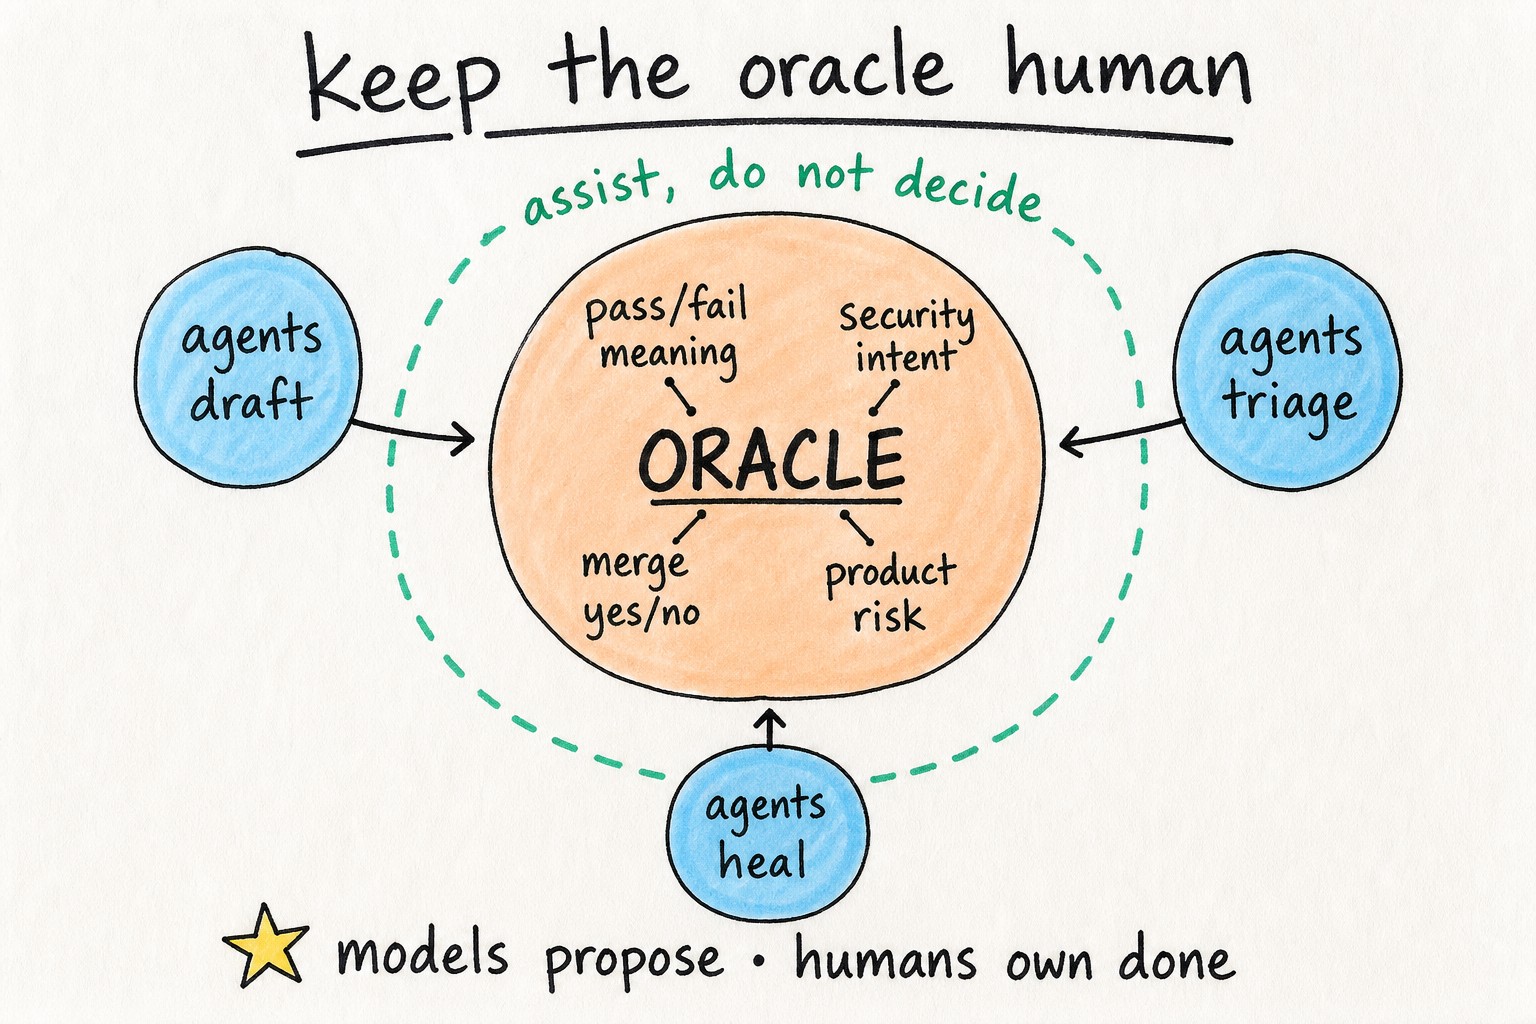
Three ownership lines stay human on our floor.
Oracle ownership. A person decides what “done” means: acceptance criteria that start red, fixtures that encode business truth, deny-lists for claims we do not trust. The agent can propose. It does not get to redefine the pass bar after it fails.
Security intent. Threat models, abuse cases, and “who can call this tool with which scope” are not vibes for a mid-tier model to invent during a Friday PR. AI can draft a checklist. A named human still owns the call on identity, secrets, and blast radius.
Merge authority. Deterministic gates and accountable reviewers merge. An LLM summary is evidence, not a vote. Healers and judges may advise. They do not press the button.
When those three blur, you get the tickets we opened with: green chat, hurt users.
A practical Bluelupin floor
On a programme that is adopting agents, we reorganise QA attention before we buy another tool logo.
- Separate generation from verification. Prefer tests and acceptance criteria that did not come from the same session that wrote the feature. Freeze oracles early.
- Keep CI deterministic. Author and heal upstream with review. Do not put a model in the merge gate.
- Tier risk on the PR. File sensitivity, test churn, and scope beat “which model wrote this.” Low can move fast. High gets human plus security.
- Instrument fake-green. Flag empty asserts, deleted cases, sudden mock growth, and healer patches that only silence failures. Track post-heal flip rate on main.
- Stand up evals where the product is AI. Golden tasks, rubrics, calibrated judges, and hard graders that override a smiling score.
- Move humans up the stack. Less time grinding the same happy path. More time on oracles, adversarial cases, production signals, and teaching agents what good evidence looks like.
We still run exploratory sessions. We still care about accessibility and performance. The difference is where scarce attention sits when the factory can emit three times the diffs.
Close
QA did not end when agents started typing. The job moved. Under higher speed, someone still has to own which proofs count, which greens are theatre, which product behaviours need harnesses instead of clicks, and which decisions stay human even when a model sounds sure.
Release velocity will keep rising. Bug shape will keep getting sneakier. The teams that hold the line will treat verification as a product of its own, with roles and techniques matched to the three shifts, not a single plugin pitched as a replacement for judgment.
We still stamp the release. We just stopped pretending every green checkmark earned the stamp.